
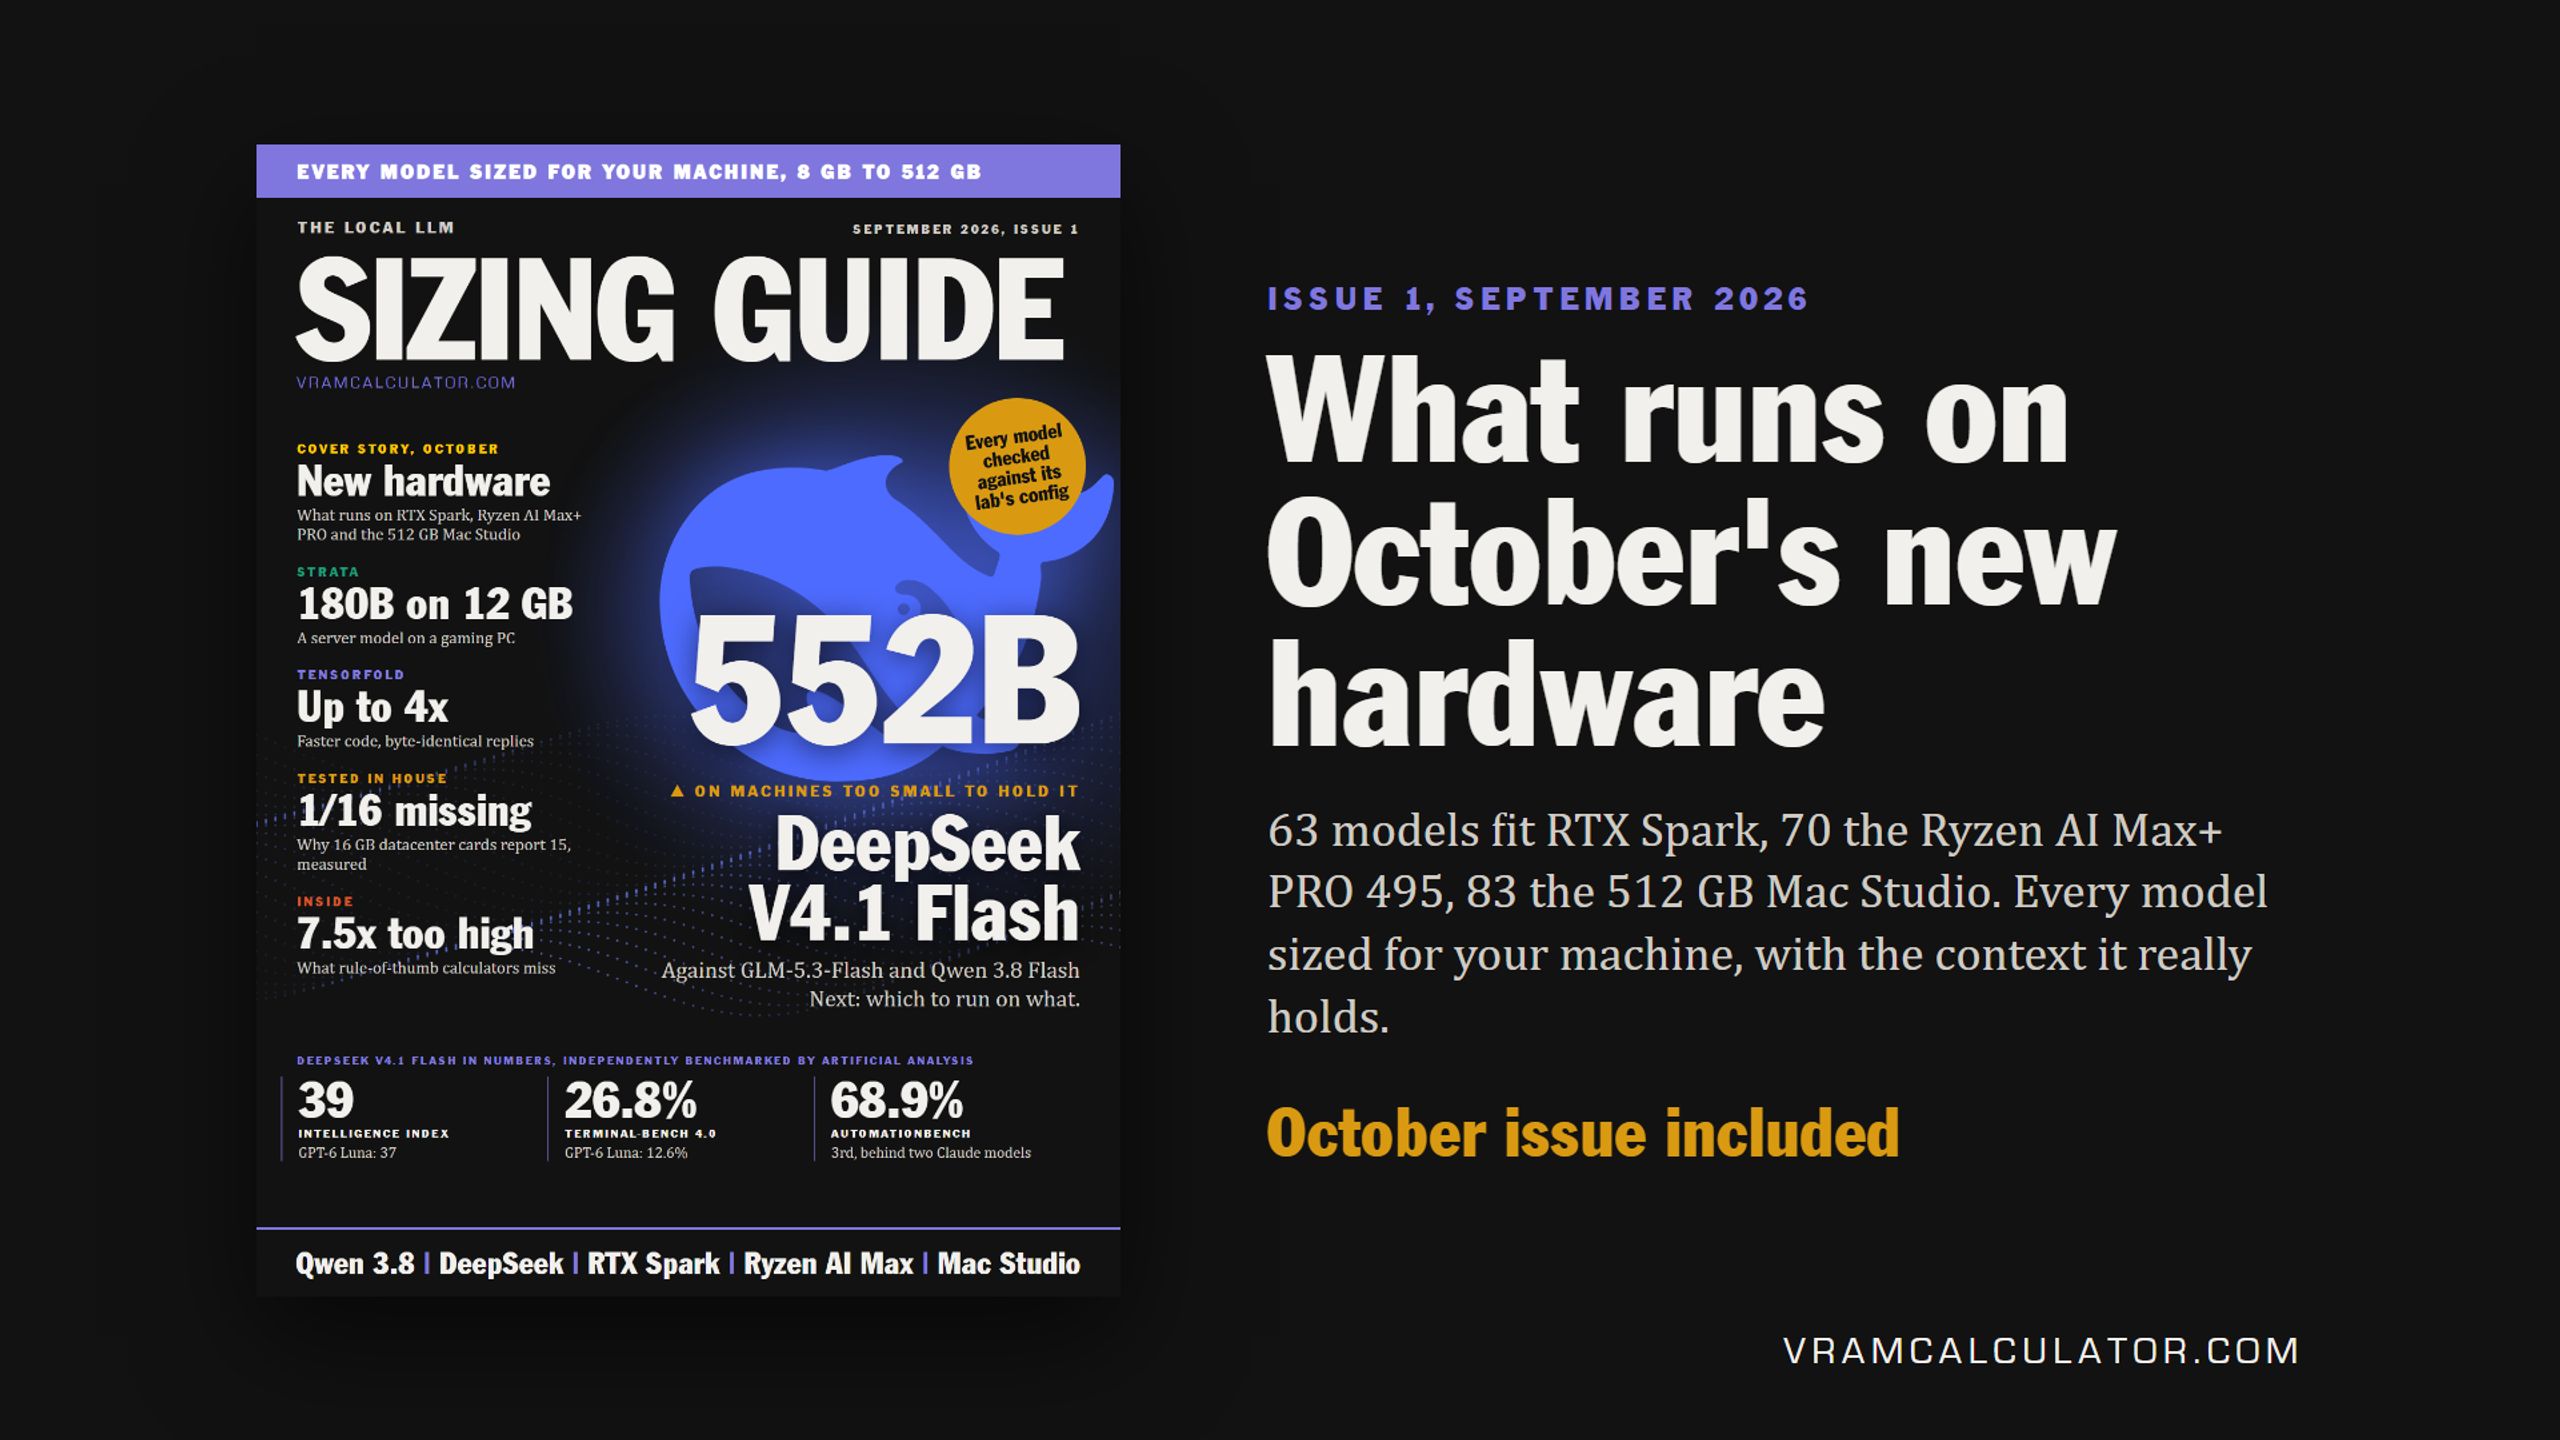
The Local LLM Sizing Guide
What every local model runs on your next GPU, Spark or Mac, 8 GB to 512 GB.
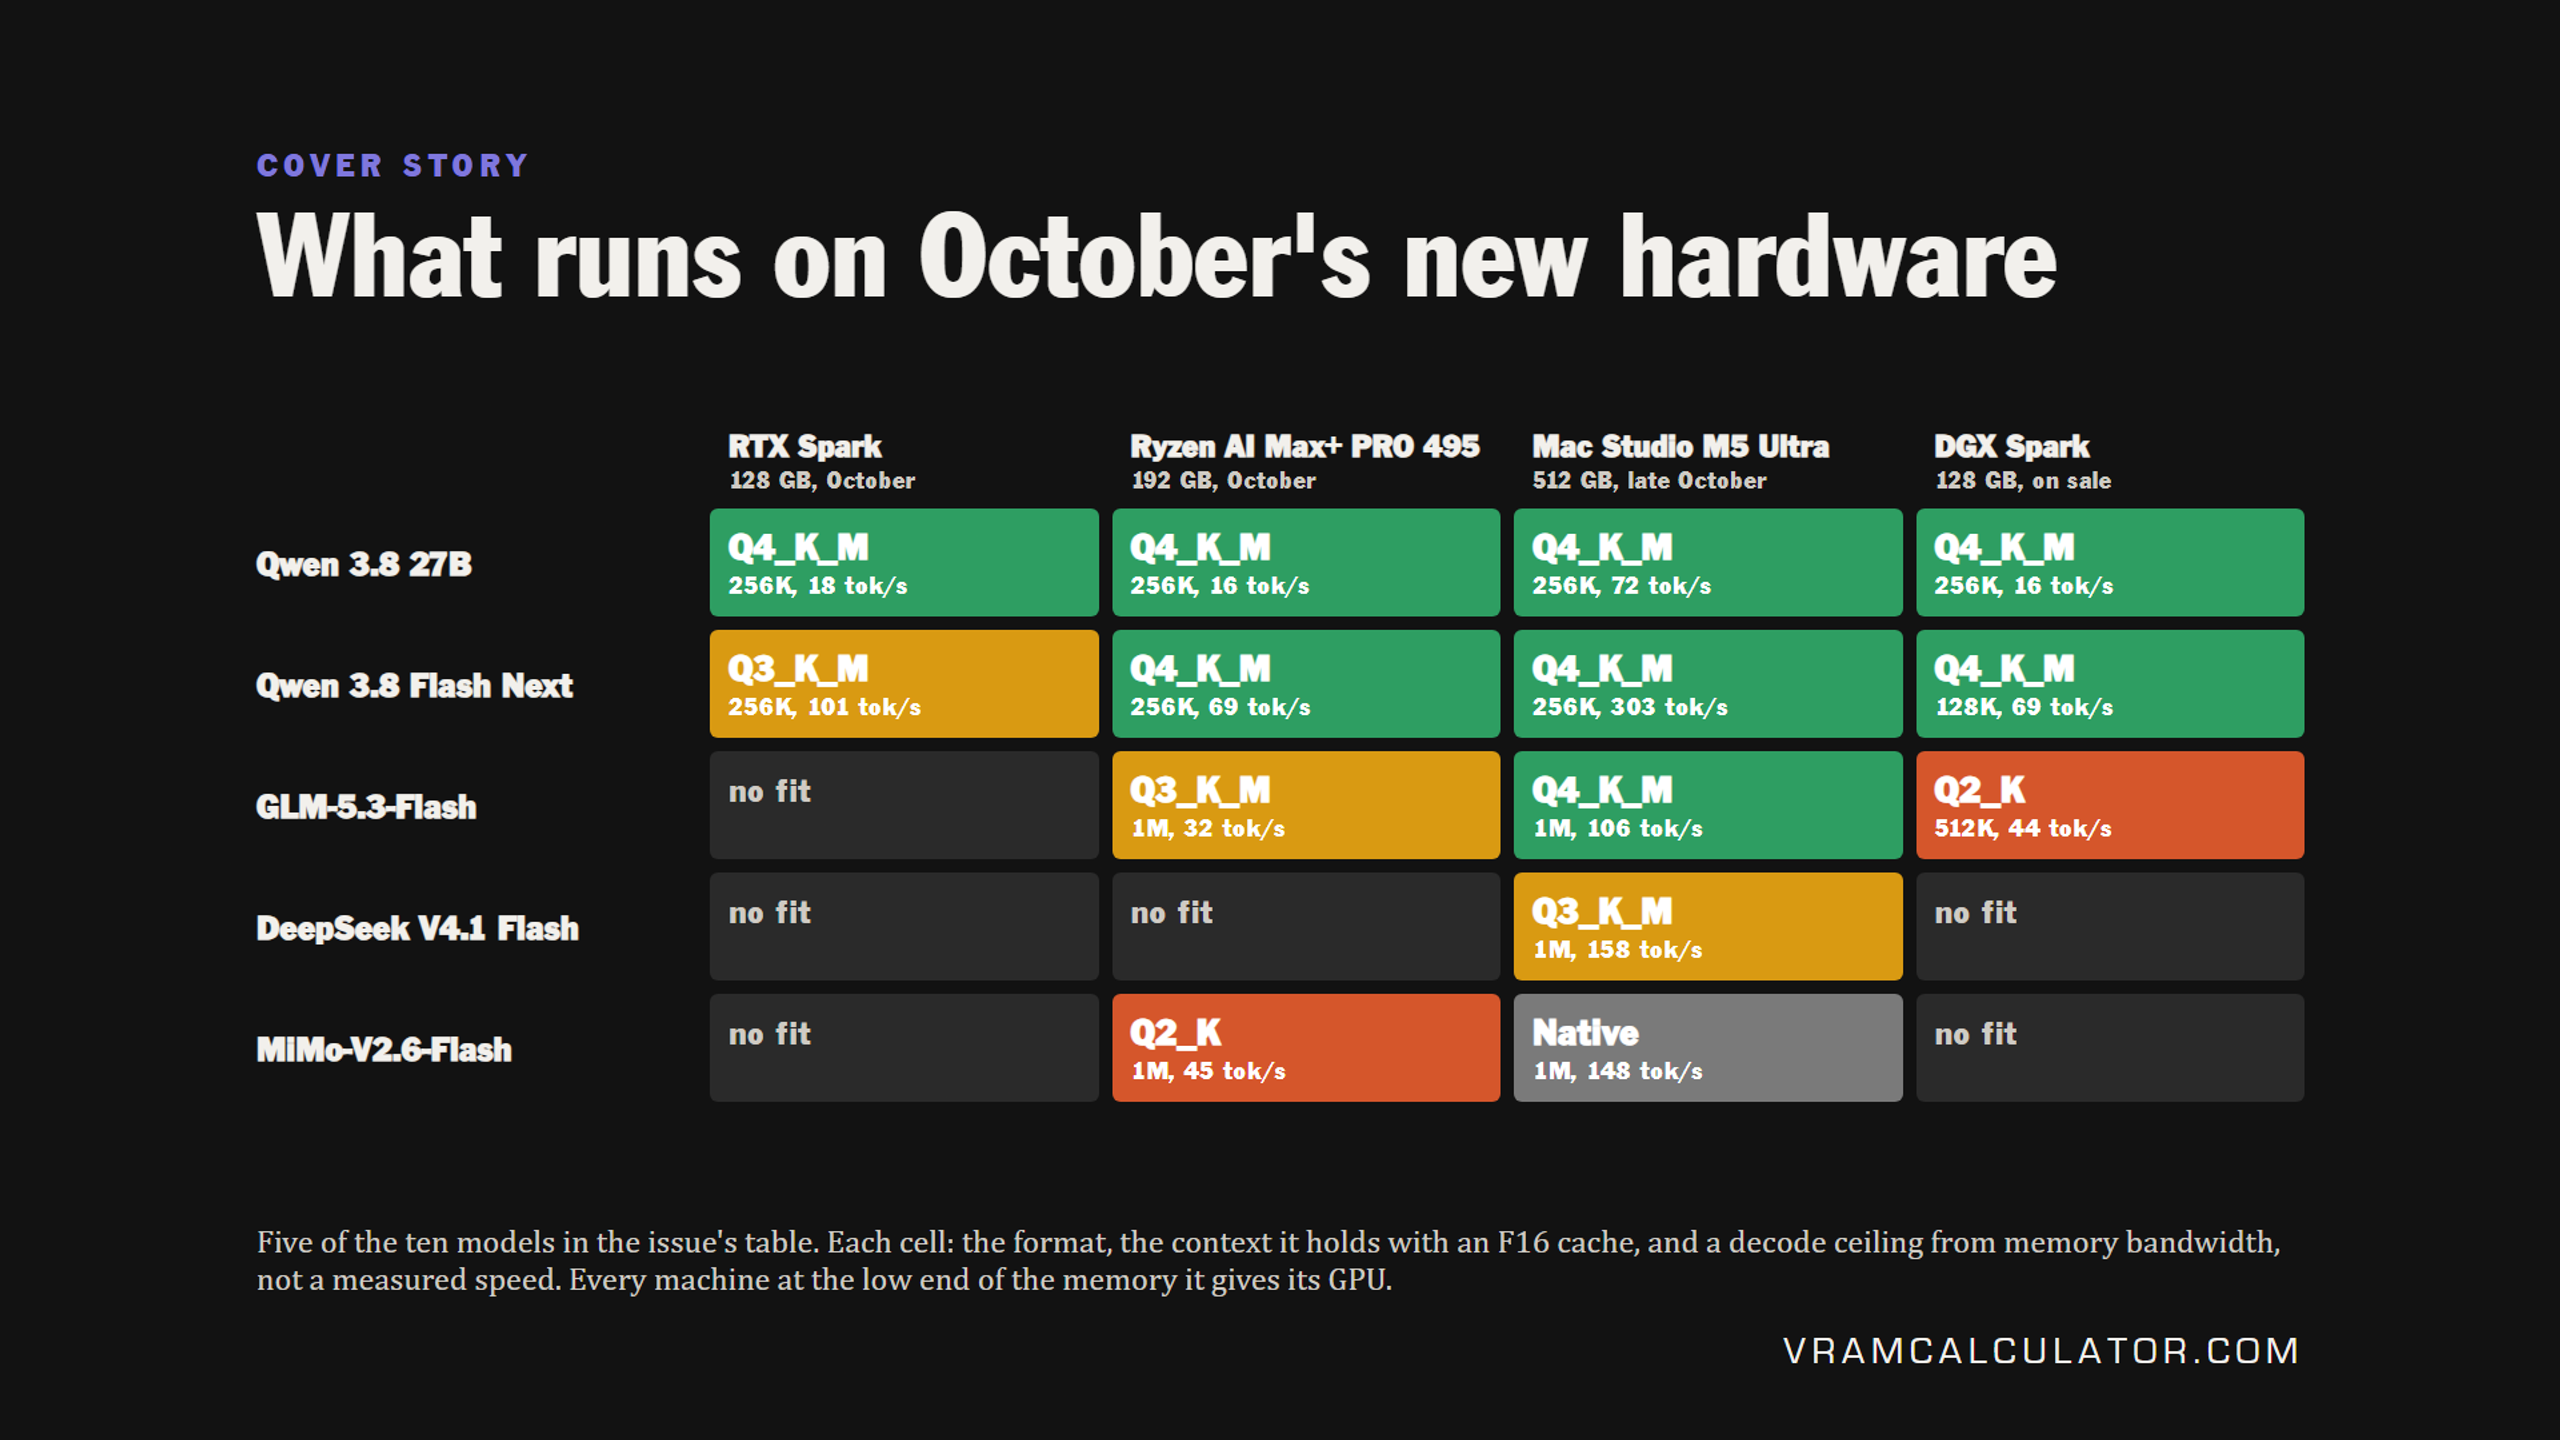
What runs on October’s new hardware? Issue 1 answers it before the machines ship: 63 models fit RTX Spark at 128 GB, 70 fit the 192 GB Ryzen AI Max+ PRO 495, 83 fit the 512 GB Mac Studio, each with the format and the context it holds.
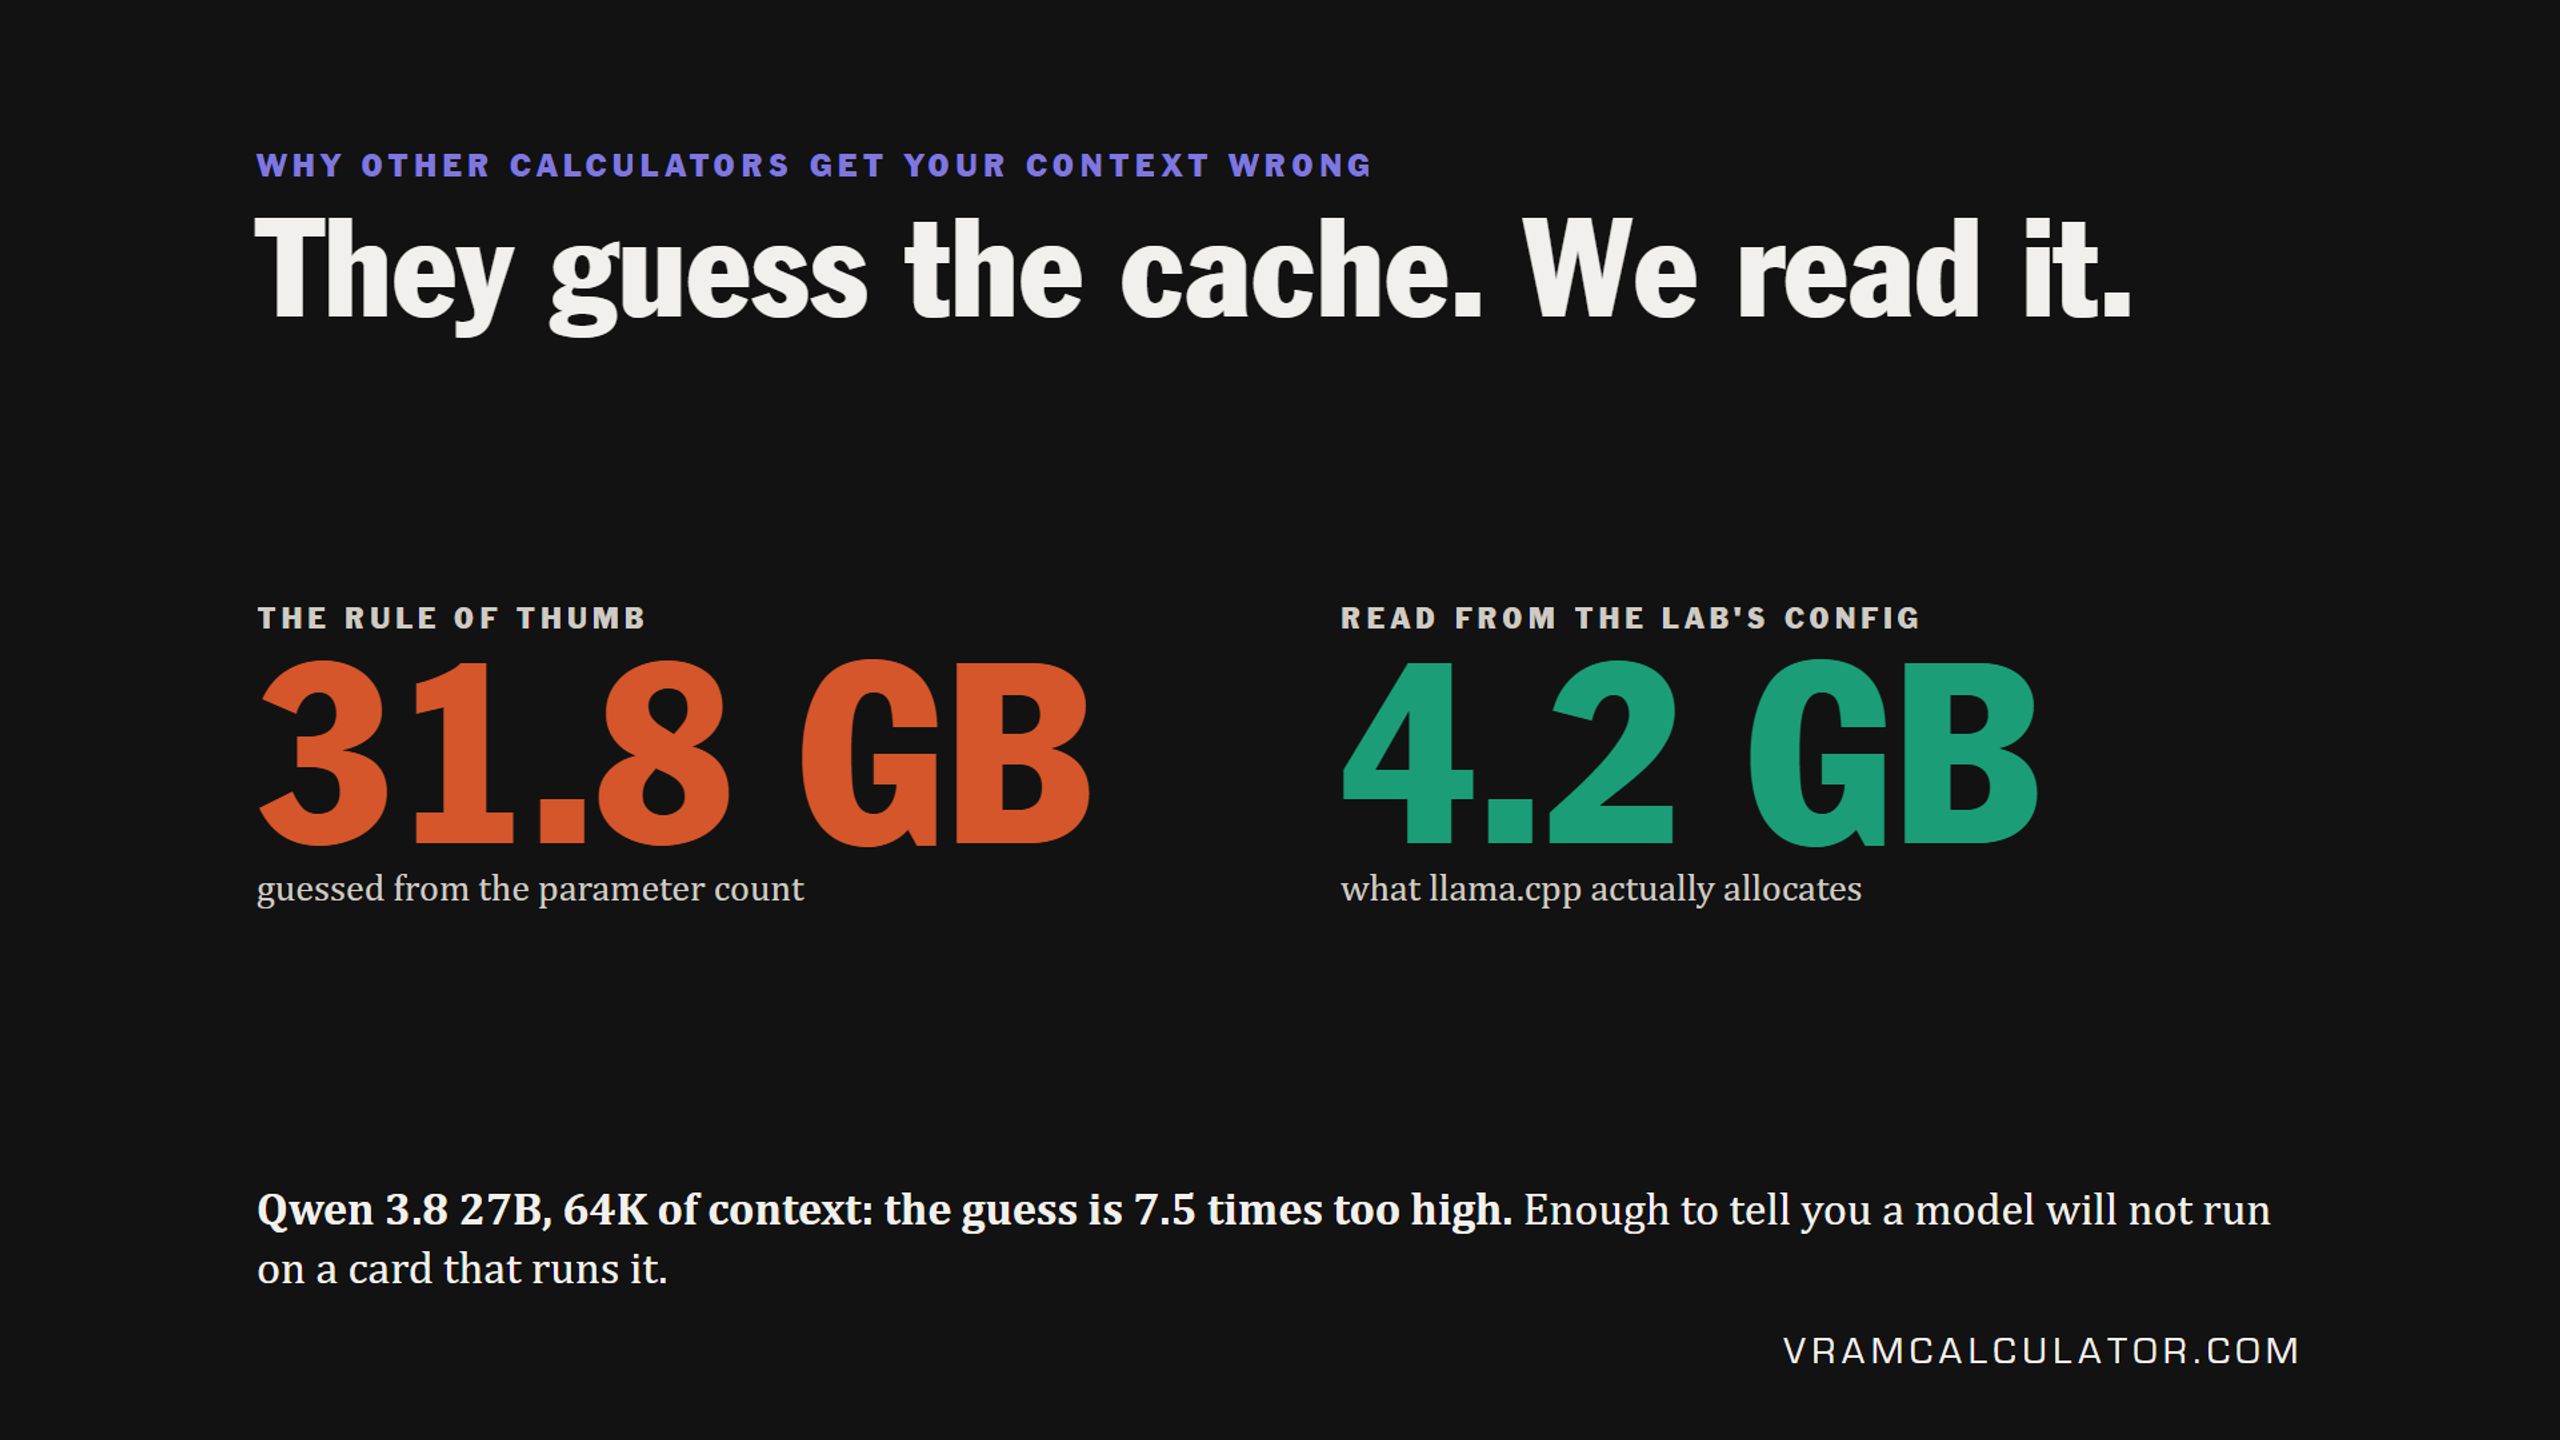
Other calculators guess your context. This guide reads it from each lab’s config. A popular rule of thumb budgets 31.8 GB of cache for Qwen 3.8 27B at 64K; llama.cpp needs 4.2 GB, a guess 7.5 times too high.
Inside Issue 1:
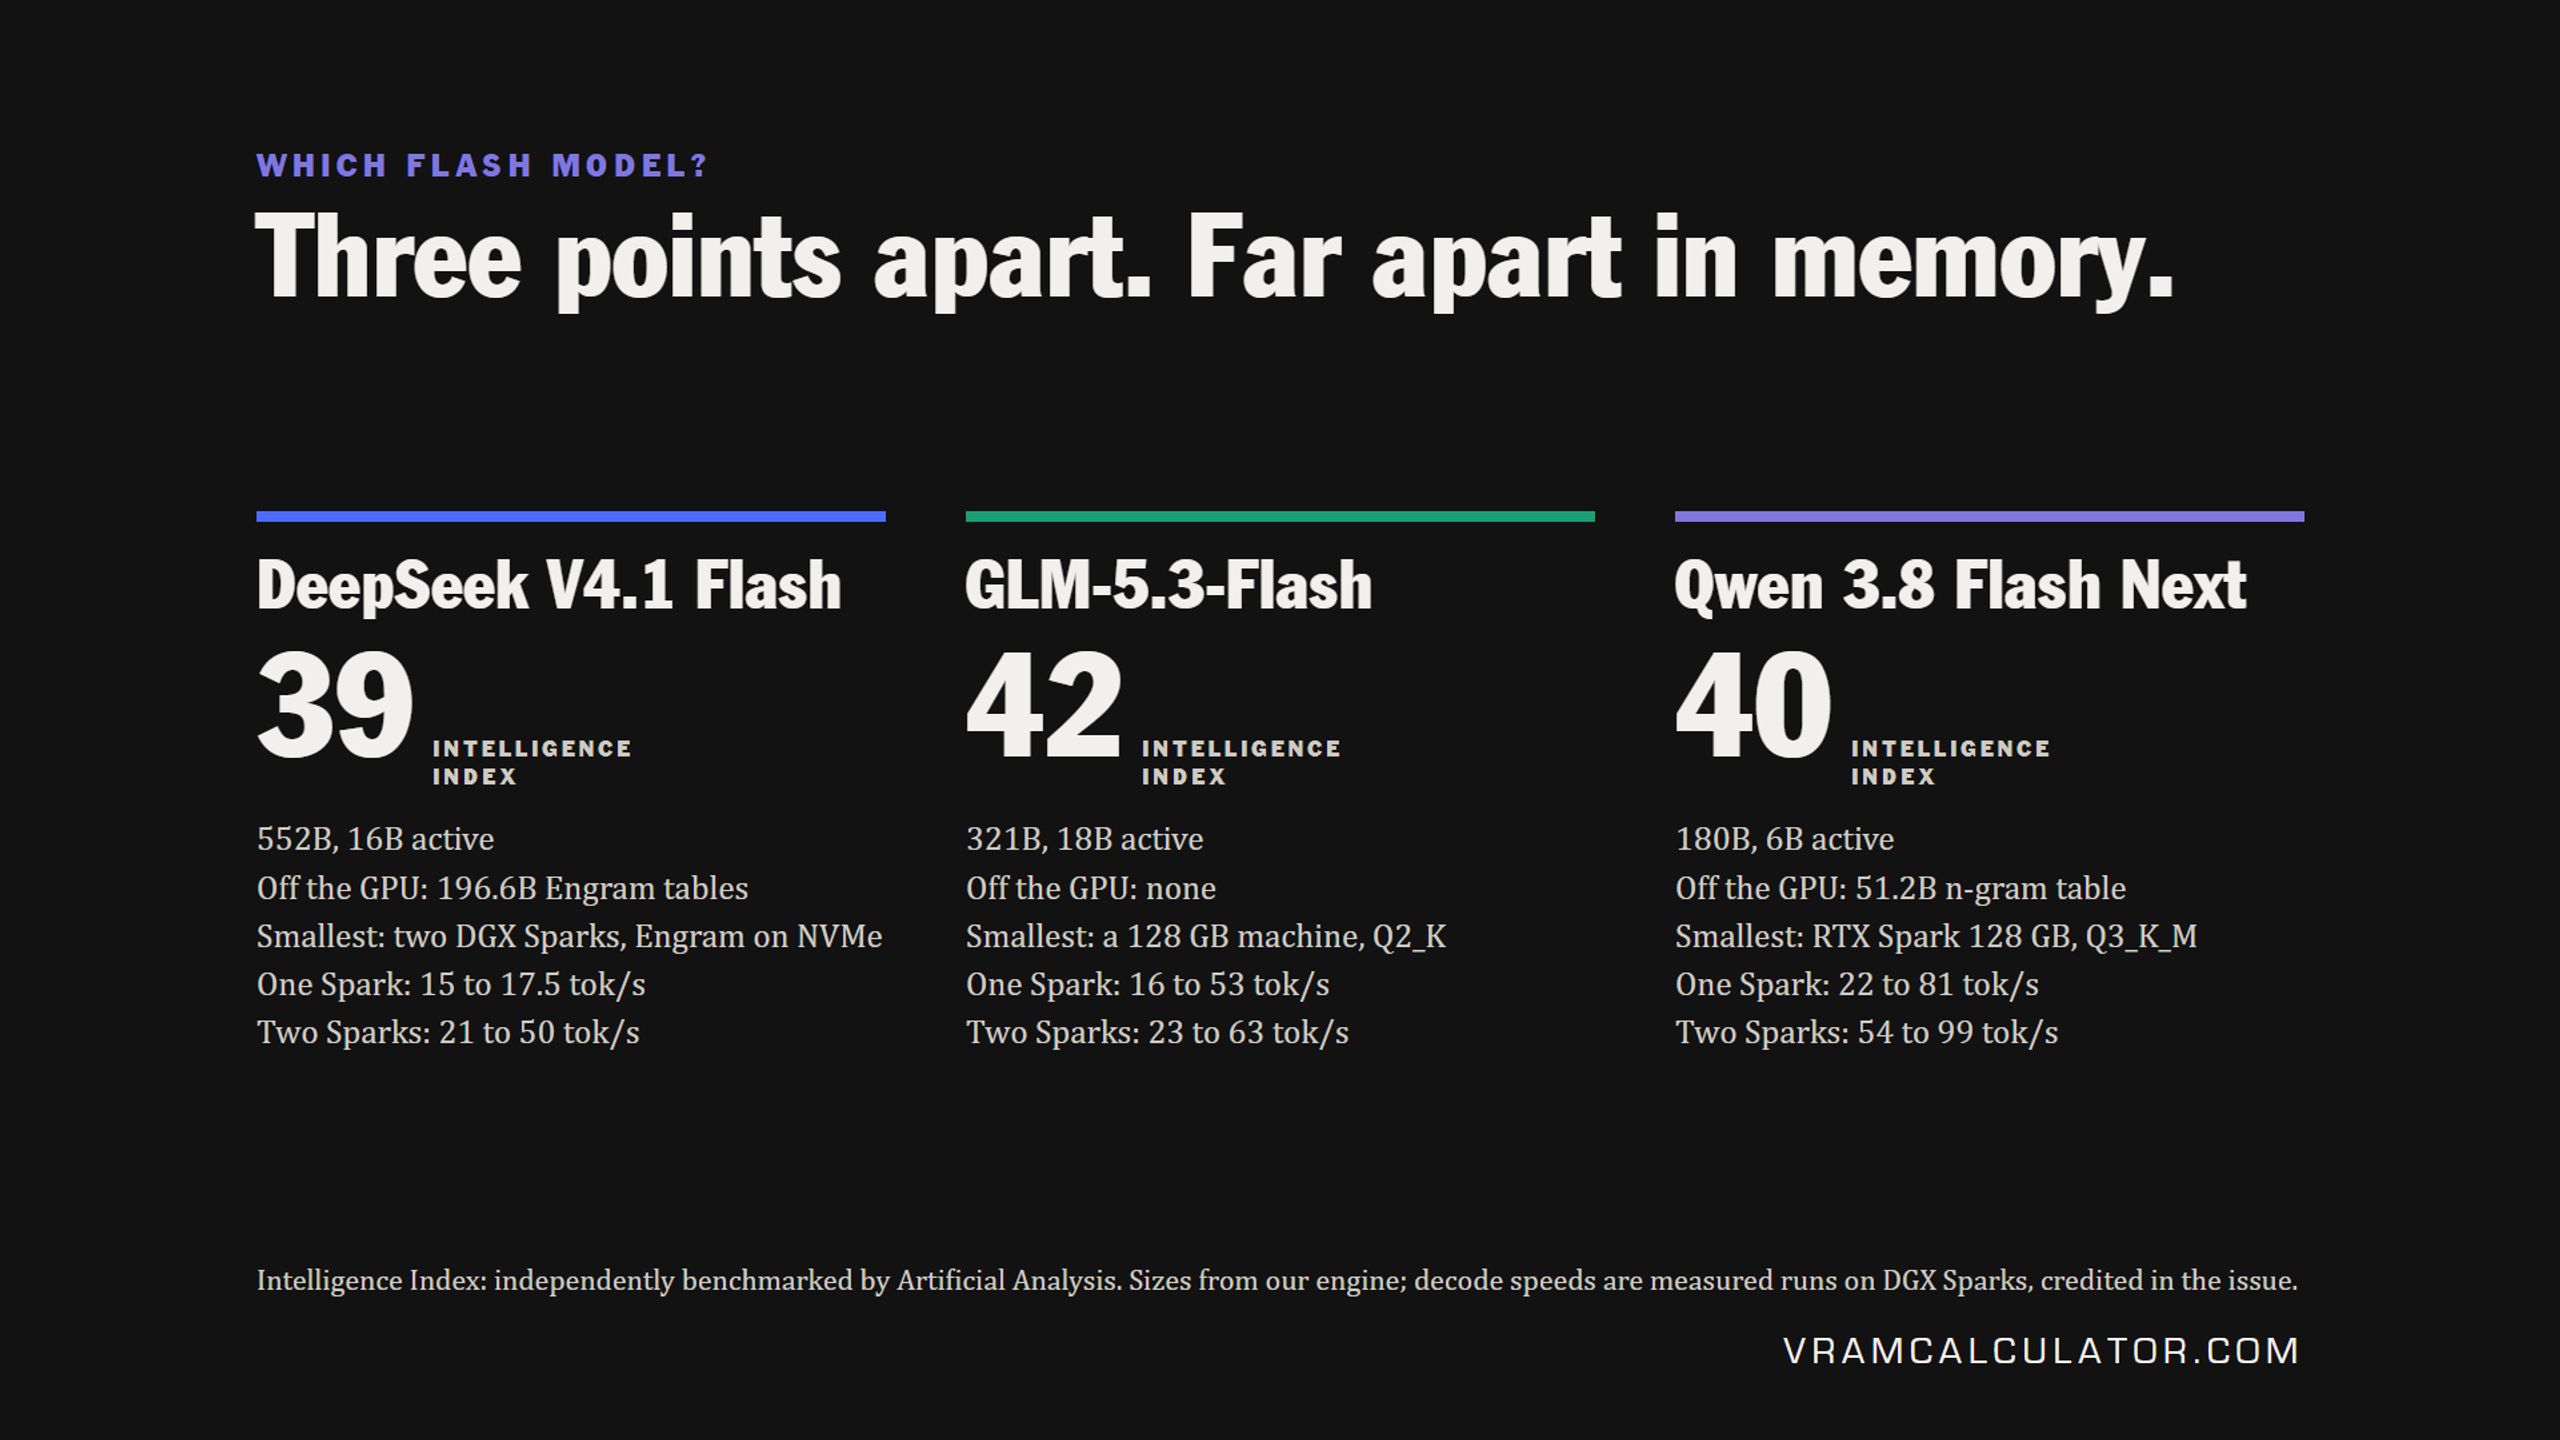
DeepSeek V4.1 Flash, GLM-5.3-Flash or Qwen 3.8 Flash Next: three points apart on Artificial Analysis’s Intelligence Index, far apart in memory. Which to run on one Spark, two Sparks or a 512 GB Mac Studio, from measured runs.
Every model on eight unified-memory machines, from the 64 GB RTX Spark chip to the 512 GB Mac Studio.
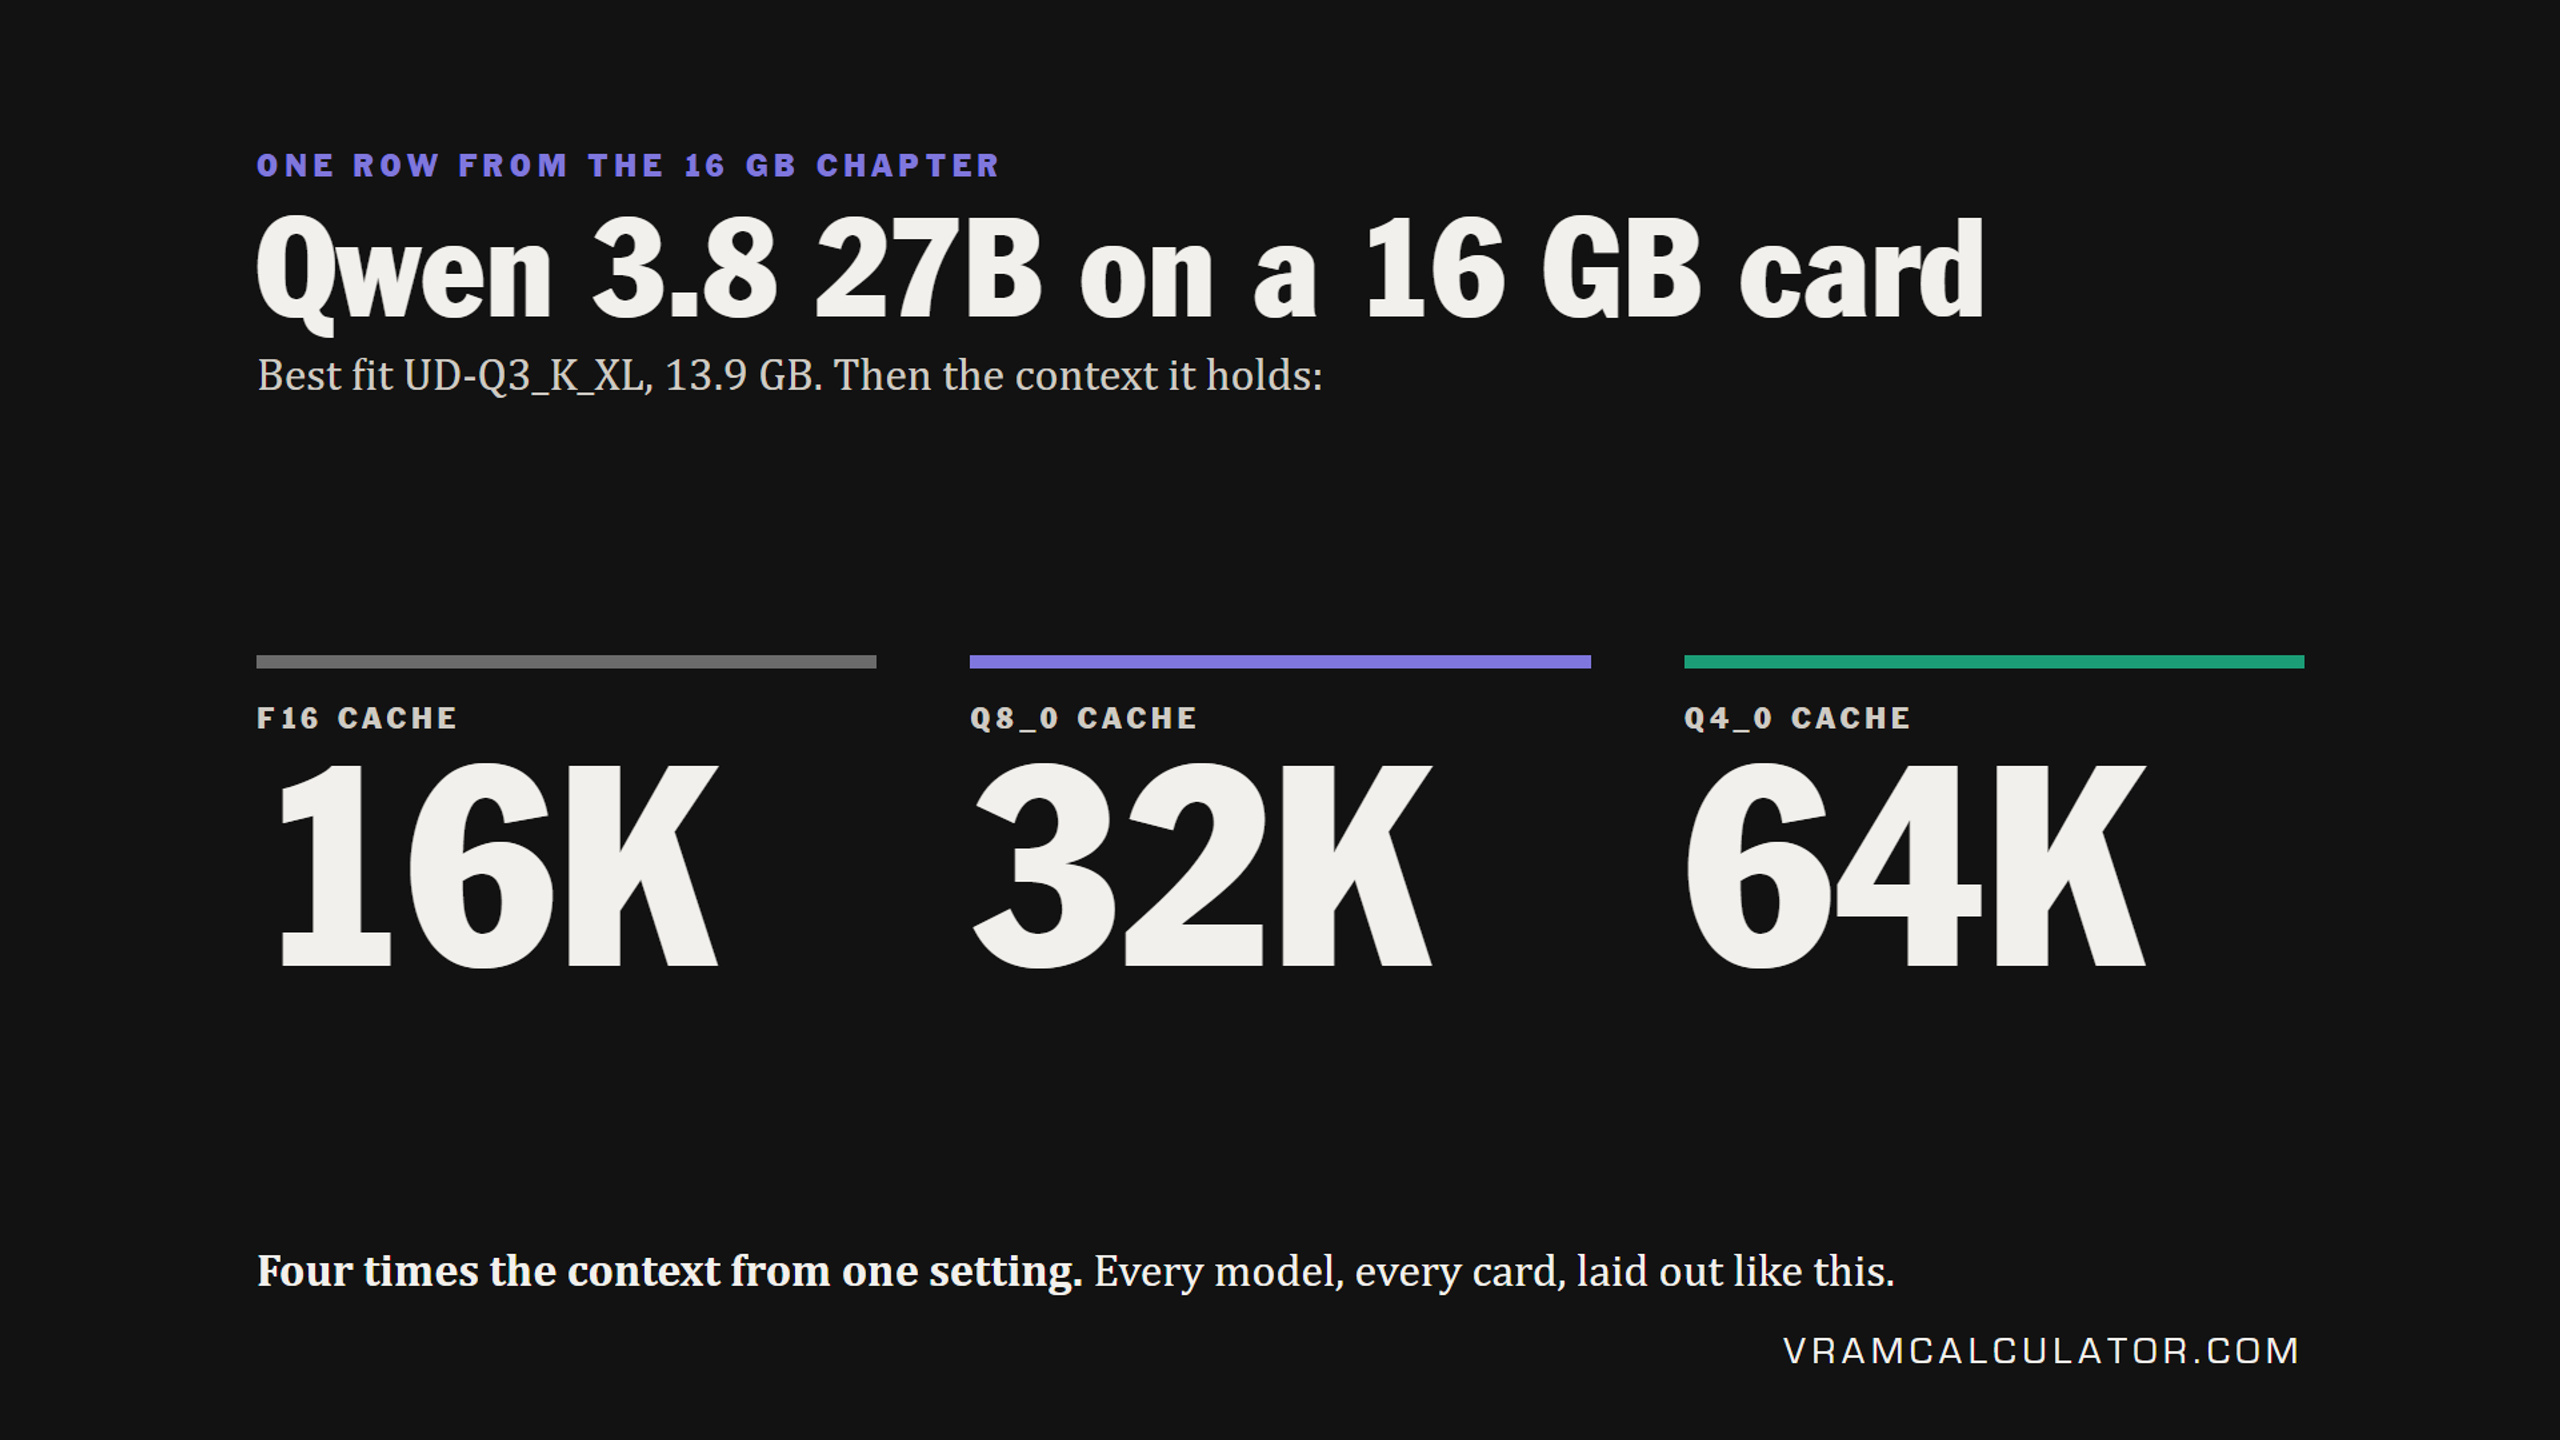
Every tier from 8 GB to 128 GB: the best quantization, and the context it holds with an F16, Q8_0 or Q4_0 cache.
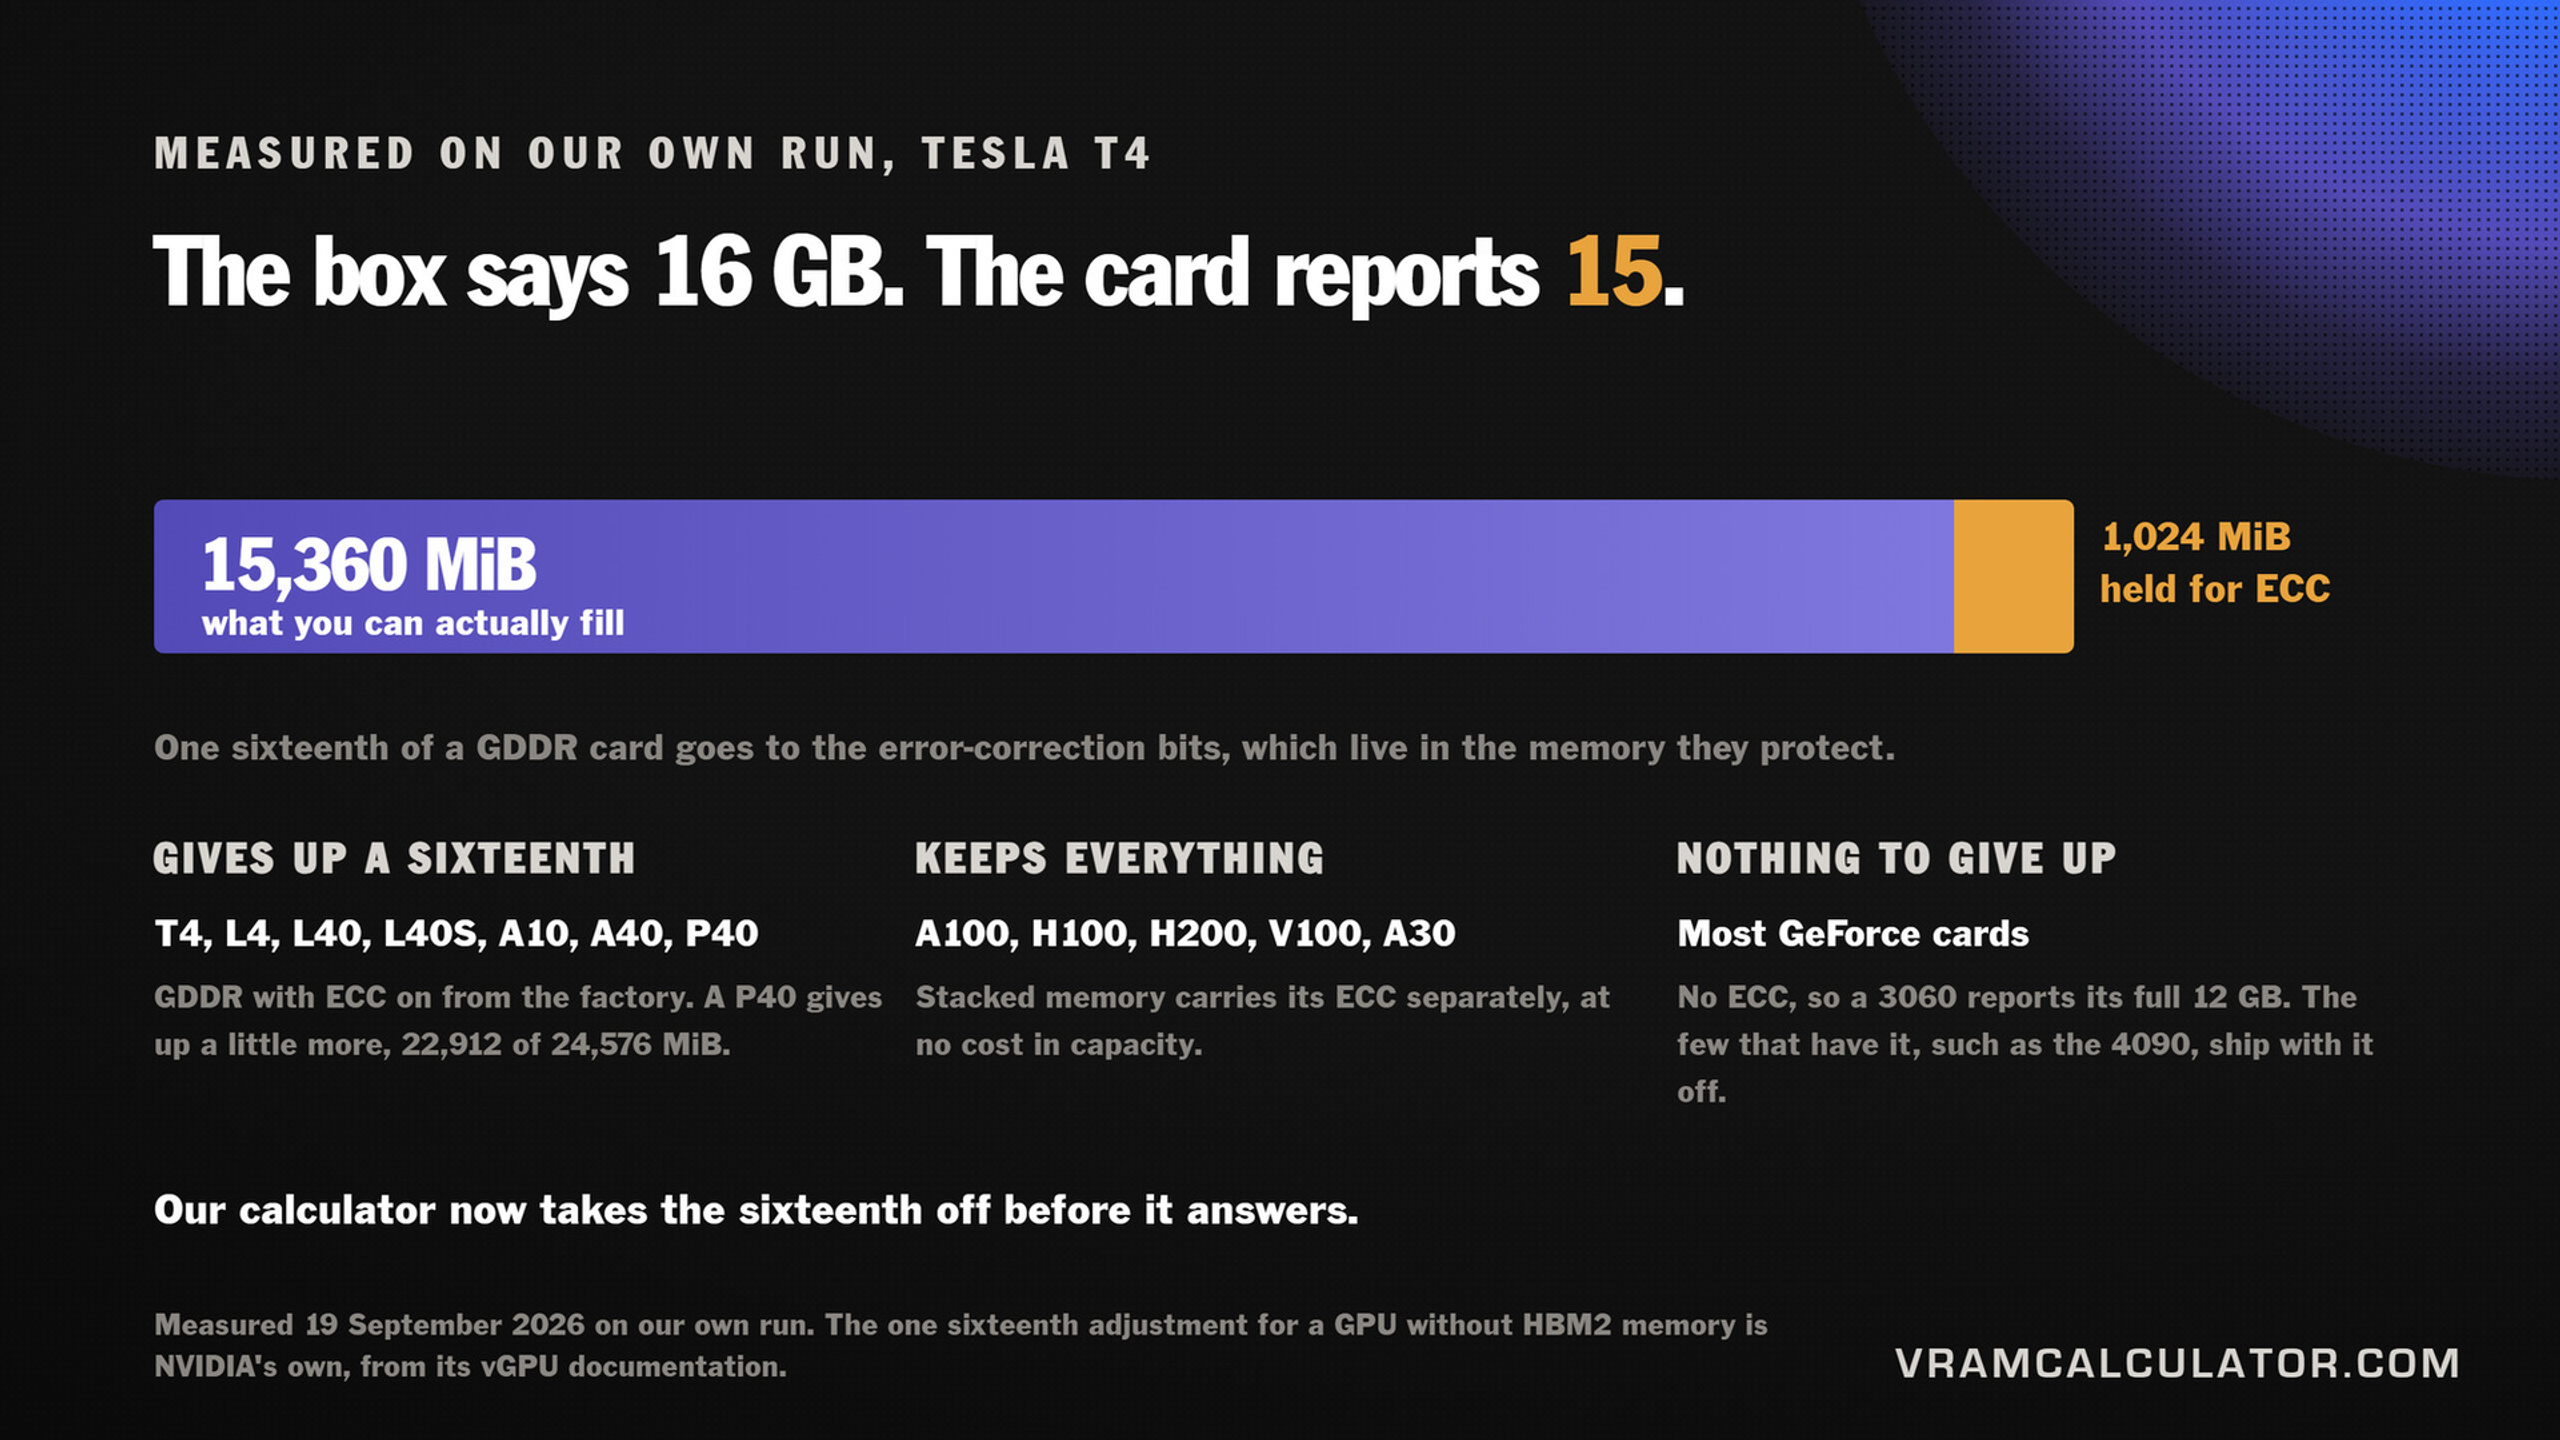
Tested in house: our own runs on a T4 and an A100, including the sixteenth of memory a datacenter card keeps for ECC.
The month’s releases, sized, with every outside measurement credited to the person who ran it.
Every model checked against its lab’s own config file.
A 67-page PDF in your Whop library as soon as you pay. The October issue is included.